Confluent Cloud costs: shrink spare Dedicated CKUs
Published · Updated · OhChimp Engineering
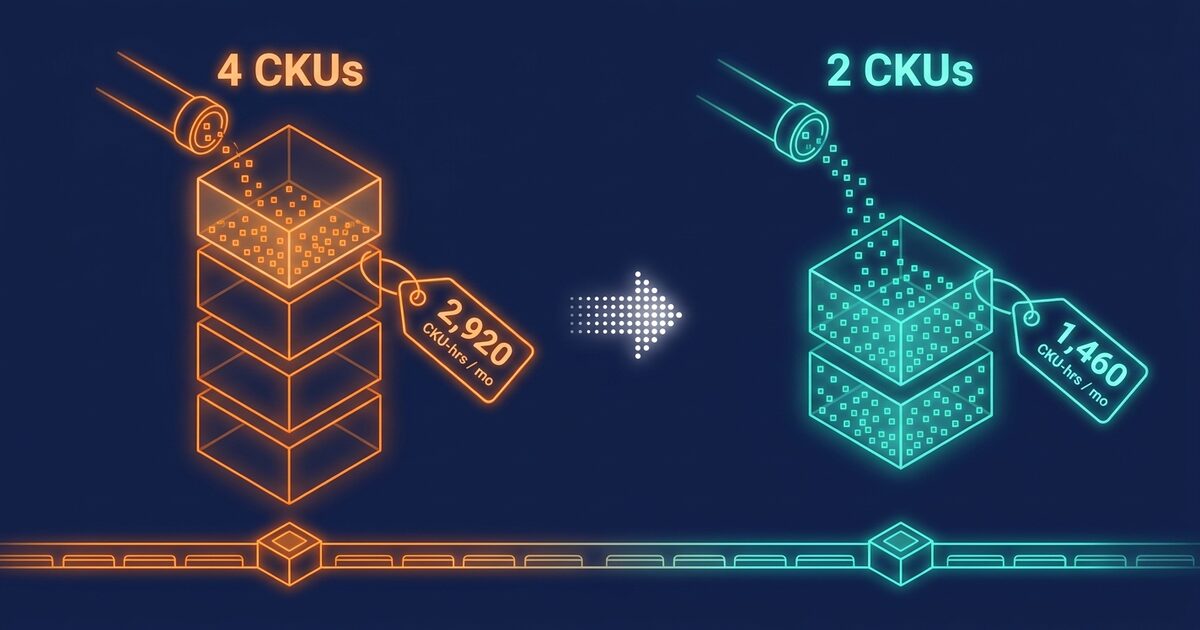
A Dedicated Confluent Cloud cluster bills for the CKUs you configured, every hour, whether your producers send a gigabyte or nothing at all. A multi-zone cluster cannot drop below 2 CKUs, which is 1,460 CKU-hours a month, and every CKU you hold above your measured peak adds another 730.
Why a Confluent Dedicated cluster costs more than its traffic
Confluent Cloud sells Kafka capacity in two units. Dedicated clusters use the CKU, the Confluent Unit for Kafka. You set the count when you create the cluster, and according to Confluent's billing dimensions the CKU line accrues on configured capacity, so an idle Dedicated cluster pays its full CKU cost. Basic, Standard, Enterprise and Freight clusters use the eCKU, an elastic unit. For each hour you are billed the highest eCKU count the cluster actually used in that hour, down to a per-type minimum, and a cluster with zero consumption on every dimension pays nothing at all.
Confluent Cloud pricing and capacity: eCKU vs CKU
Both units are sized against the same published limits. Here is what one unit holds on the three types you are most likely to be choosing between, from Confluent's cluster types reference:
| Per unit | Standard eCKU | Enterprise eCKU | Dedicated CKU |
|---|---|---|---|
| Ingress | 25 MBps | 60 MBps | 60 MBps |
| Egress | 75 MBps | 180 MBps | 180 MBps |
| Partitions | 250 | 3,000 (1,000 compacted) | 4,500 |
| Client connections | 1,000 | 18,000 | 18,000 |
| Requests per second | 1,500 | 7,500 | 15,000 |
On throughput and connections an Enterprise eCKU and a Dedicated CKU are the same size, so the difference is almost entirely in how the hours are counted. A Dedicated cluster sized for a two-hour peak bills that peak for all 730 hours of the month.
Confluent Cloud's pricing page lists public prices for the elastic types only. On 13 September 2026 it showed Standard at $0.75 per eCKU-hour and Enterprise at $1.75 to $2.25, and Confluent notes that prices vary by cloud region. Confluent does not publish a public price for the Dedicated CKU, so the rate for your account comes from the Confluent CLI:
confluent billing price list --cloud aws --region us-east-1 \
  --cluster-type dedicated --metric KafkaNumCKUs
Swap in your cluster's cloud and region, and add --network-type (internet, peered-vpc, private-link or transit-gateway) if you want the list narrowed further. That gives you the list rate. The rate you actually pay after a commit discount comes out of the Costs API in the next section.
Four-nines clusters floor at the same size on both sides. The 99.99% uptime SLA needs a multi-zone Dedicated cluster, which requires at least 2 CKUs, or a Standard or Enterprise cluster with a minimum of 2 eCKUs. Above that floor, Dedicated bills its configured count every hour while an elastic cluster bills each hour at that hour's peak.
If your Confluent Cloud organization was created before 16 April 2024, Basic and Standard clusters still bill on the legacy model, per partition plus an hourly base price on Standard, so the Standard eCKU rate above is the wrong comparison for you.
You cannot downgrade Dedicated to Enterprise or Standard
Confluent supports exactly one cluster type change in place, upgrading Basic to Standard. No console button, CLI flag or API field turns a Dedicated cluster into an Enterprise or Standard one. You get two moves: shrink the CKU count on the cluster you have, or build a new elastic cluster and move every client onto it.
The CLI removes capacity one CKU at a time, and Confluent blocks a shrink that would put the cluster over the per-CKU partition or throughput limits at the new size. Each step rebalances partitions onto the remaining brokers and typically takes 30 to 60 minutes per CKU, and a second resize cannot start until the first one finishes. Billing moves to the new count in the hour after the change.
Growing back is the slow direction. An expansion provisions capacity first, which typically takes under two hours and is excluded from the SLA, and only then rebalances. That rules out resizing on a daily schedule to follow your traffic, and it sets the lead time on every rollback.
Leaving Dedicated runs into five constraints:
- Cluster Linking only writes into Dedicated, Enterprise or Freight clusters (Freight only on AWS with private networking). Basic and Standard cannot be a link's destination, so a move to Standard means MirrorMaker 2, a dual-write period, or letting old data age out, instead of a byte-for-byte mirror with preserved offsets.
- Enterprise clusters are private networking only. They take PrivateLink or Private Network Interface. A Dedicated cluster your clients reach over the public internet, VPC peering or Transit Gateway needs every client's network path rebuilt before cutover, and a privately networked Dedicated cluster has no Standard option at all, because Standard is public only.
- Enterprise eCKUs hold fewer compacted partitions. Each eCKU supports 3,000 partitions, of which 1,000 can be compacted, while a Dedicated CKU allows all 4,500 to be compacted. A cluster carrying 2,500 compacted partitions sits inside one CKU's limit and needs 3 Enterprise eCKUs. Kafka Streams changelog topics are compacted, so count them.
- Mirror topics do not support transactions. Confluent does not support Cluster Linking for topics written with transactions or exactly-once semantics, so an exactly-once Kafka Streams application needs its own cutover plan.
- A Kafka API key belongs to its cluster. A cluster-scoped key works only on the cluster it was created for, so the new cluster needs new keys and every client needs the new bootstrap endpoint. Global API keys can span Dedicated and Enterprise clusters, but they do not work on Basic or Standard.
Find your oversized Dedicated clusters by hand
Everything below authenticates with a Cloud API key over HTTP basic auth. Reading costs needs the key's owner to hold OrganizationAdmin or BillingAdmin, and the Metrics API needs MetricsViewer.
The cluster list is scoped to one environment per call, so start by walking every environment:
export CC_KEY=... CC_SECRET=...
API=https://api.confluent.cloud

for env in $(curl -s -u "$CC_KEY:$CC_SECRET" "$API/org/v2/environments?page_size=100" \
             | jq -r '.data[].id'); do
  curl -s -u "$CC_KEY:$CC_SECRET" \
    "$API/cmk/v2/clusters?environment=$env&page_size=100" \
  | jq -r --arg env "$env" '.data[]
      | select(.spec.config.kind == "Dedicated")
      | [$env, .id, .spec.display_name, .spec.availability,
         .spec.cloud, .spec.region, (.spec.network.id // "internet"), .status.cku]
      | @tsv'
done
status.cku is the count the cluster has right now, and availability reads SINGLE_ZONE or MULTI_ZONE. A MULTI_ZONE cluster at 2 CKUs is already on its floor, so only a move to an elastic type changes its bill. Both lists return up to 100 items a page, so follow metadata.next if your org is bigger than that.
Next, pull what each cluster cost last month. The Costs API returns daily lines, accepts a window of one month at most, and can take up to 72 hours to catch up, so query a closed month. It pages, so follow metadata.next until it runs out:
url="$API/billing/v1/costs?start_date=2026-08-01&end_date=2026-09-01&page_size=500"
: > costs.jsonl
while [ -n "$url" ]; do
  page=$(curl -s -u "$CC_KEY:$CC_SECRET" "$url")
  echo "$page" | jq -c '.data[]' >> costs.jsonl
  url=$(echo "$page" | jq -r '.metadata.next // empty')
done

# cluster, unit-hours, billed dollars, effective dollars per unit-hour
jq -rs '[.[] | select(.line_type == "KAFKA_NUM_CKUS")]
  | group_by(.resource.id)
  | map({cluster: .[0].resource.id,
         unit_hours: (map(.quantity) | add),
         billed: (map(.amount) | add)})
  | map(select(.unit_hours > 0) | . + {rate: (.billed / .unit_hours)})
  | sort_by(-.billed)[]
  | [.cluster, .unit_hours, (.billed * 100 | round / 100), (.rate * 1000 | round / 1000)]
  | @tsv' costs.jsonl
KAFKA_NUM_CKUS is the capacity line for every cluster type, CKUs and eCKUs alike, so match the IDs against the Dedicated list from the first step. amount is the figure after discounts, which makes the last column your effective CKU-hour rate. Keep it for the Enterprise comparison further down.
For traffic, the Metrics API keeps seven days of data at one-minute resolution, and it rejects a one-minute query spanning more than six hours. So find the busiest hours first, then look inside one of them minute by minute:
LKC=lkc-xxxxx
q() {  # q <metric> <granularity> <interval>
  curl -s -u "$CC_KEY:$CC_SECRET" -H 'Content-Type: application/json' \
    -X POST https://api.telemetry.confluent.cloud/v2/metrics/cloud/query \
    -d "$(jq -n --arg m "$1" --arg g "$2" --arg i "$3" --arg c "$LKC" \
      '{aggregations: [{metric: $m}],
        filter: {field: "resource.kafka.id", op: "EQ", value: $c},
        granularity: $g, intervals: [$i]}')"
}

# The five busiest hours of the past week by bytes produced, as average MBps
q io.confluent.kafka.server/received_bytes PT1H 'now-7d|h/now-1h|h' \
  | jq -r '.data | sort_by(-.value)[:5][] | [.timestamp, (.value / 3600 / 1e6 * 10 | round / 10)] | @tsv'

HOUR=2026-09-10T14:00:00Z   # paste a timestamp from the list above
peak() { q "io.confluent.kafka.server/$1" PT1M "$HOUR/PT1H" | jq '[.data[].value] | max // 0'; }

echo "ingress MBps  $(peak received_bytes | jq '. / 60 / 1e6 * 10 | round / 10')"
echo "egress MBps   $(peak sent_bytes | jq '. / 60 / 1e6 * 10 | round / 10')"
echo "requests/s    $(peak request_count | jq '. / 60 | round')"
echo "connections   $(peak active_connection_count)"
echo "load, avg     $(peak cluster_load_percent_avg)"
echo "load, max $(peak cluster_load_percent_max)"received_bytes, sent_bytes and request_count are counts per one-minute sample, which is why they get divided by 60. The load metrics exist only on Dedicated clusters and read 0.0 to 1.0. If you run Cluster Linking, sent_bytes includes bytes mirrored out of the cluster while received_bytes leaves out bytes mirrored in.
A month-end batch or a quarterly load test can fall entirely outside a seven-day window, so save these numbers on a schedule before you trust a quiet week.
Partitions come from the cluster's own REST endpoint and need a Kafka API key for that cluster:
ENV=env-xxxxx
REST=$(curl -s -u "$CC_KEY:$CC_SECRET" "$API/cmk/v2/clusters/$LKC?environment=$ENV" \
       | jq -r '[.spec.endpoints[]][0].http_endpoint')

curl -s -u "$KAFKA_KEY:$KAFKA_SECRET" "$REST/kafka/v3/clusters/$LKC/topics" > topics.json
curl -s -u "$KAFKA_KEY:$KAFKA_SECRET" "$REST/kafka/v3/clusters/$LKC/topics/-/configs" > configs.json

jq '[.data[].partitions_count] | add' topics.json
jq -s '(.[1].data | map(select(.name == "cleanup.policy"
          and ((.value // "") | contains("compact")))) | map(.topic_name)) as $compacted
  | .[0].data | map(select(.topic_name | IN($compacted[])) | .partitions_count) | add // 0' \
  topics.json configs.json
The first number is total partitions and the second is the compacted share. On a privately networked cluster, run these from inside the network that can reach it.
Divide each peak by its per-CKU figure from the table (60 MBps in, 180 MBps out, 4,500 partitions, 18,000 connections, 15,000 requests a second), take the largest ratio, and round up. That is the CKU count your busiest minute needed, with a floor of 2 on a multi-zone cluster.
Say a multi-zone cluster runs 4 CKUs, and its busiest minute last week showed 41 MBps in, 96 MBps out, 2,300 partitions, 5,200 connections and 8,100 requests a second. Those come to 0.68, 0.53, 0.51, 0.29 and 0.54 of one CKU. Ingress is the tightest dimension and it still fits inside a single CKU, so the multi-zone floor of 2 is the answer. Going from 4 CKUs to 2 takes the cluster from 2,920 CKU-hours a month to 1,460, which halves the capacity line, and leaves that peak at about a third of the smaller cluster's ingress guideline.
Those ratios are a first cut. Confluent publishes partitions and connection attempts as fixed limits, while throughput, connections and requests are guidelines that depend on the rest of the workload, so cluster load is the number that settles it. Confluent's own performance guidance says to expect higher latency and some throttling above 80% average load, and its consumer-lag checklist says to expand a cluster loaded above 70%. Those pages state load as a percentage while the Metrics API returns a fraction, so 80% is a cluster_load_percent_avg reading of 0.8 and 70% is 0.7. Leave the smaller cluster enough room to stay under 0.7 at your peak. A maximum load far above the average points at a hot partition instead, and removing CKUs will not cool a hot partition.
Shrink the cluster one CKU at a time
Step down one CKU from the CLI:
confluent kafka cluster update "$LKC" --environment "$ENV" --cku 3Wait for the rebalance before the next step. Confluent emails when a resize completes, and you can watch the reported count catch up with the requested one:
curl -s -u "$CC_KEY:$CC_SECRET" "$API/cmk/v2/clusters/$LKC?environment=$ENV" \
  | jq '{requested: .spec.config.cku, current: .status.cku, phase: .status.phase}'
Between steps, rerun the peak queries through your next busy hour and check your clients. A throttled producer reports non-zero produce-throttle-time-max and produce-throttle-time-avg, and a throttled consumer reports the same on fetch-throttle-time-max and fetch-throttle-time-avg. Clients can log leader elections while partitions move, which supported Kafka clients handle without a restart. Once load and throttle times look normal at 3, repeat with --cku 2.
Rollback is the same command with the old count:
confluent kafka cluster update "$LKC" --environment "$ENV" --cku 4Because an expansion provisions capacity before it rebalances, schedule a shrink right after your weekly peak, so any regrowth has days to land before the next one. If Confluent's shrink itself fails partway, the cluster expands back to its original size on its own.
When the floor is still too big, price an Enterprise cluster
A multi-zone cluster already at 2 CKUs has nothing left to shrink, and neither does a cluster whose busiest hours genuinely need every CKU it has. Elastic billing is the remaining lever when those busy hours are a small slice of the day.
Say a nightly batch needs 5 units of throughput capacity for 3 hours and less than one unit the rest of the time. A Dedicated cluster sized for it bills 5 CKUs times 730 hours, or 3,650 CKU-hours a month. A four-nines Enterprise cluster bills 5 eCKUs for those 3 hours and its 2-eCKU minimum for the other 21, which is 57 eCKU-hours a day and about 1,734 a month.
At Enterprise's list range of $1.75 to $2.25 an eCKU-hour, that is $3,034 to $3,901 a month, so Enterprise costs less once your effective CKU-hour rate from the Costs API is above $0.83 to $1.07. Run the same comparison on the per-GB ingress, egress and storage lines from both price lists, because those rates differ by cluster type too. That arithmetic holds when throughput sets the size. If partitions or requests set it, redo the ratios with Enterprise's smaller per-eCKU figures first.
If the numbers favor Enterprise, create the Enterprise cluster, then create a cluster link on it that pulls from the Dedicated cluster and syncs consumer offsets and ACLs:
DEDICATED_BOOTSTRAP=$(curl -s -u "$CC_KEY:$CC_SECRET" "$API/cmk/v2/clusters/$LKC?environment=$ENV" \
  | jq -r '[.spec.endpoints[]][0].kafka_bootstrap_endpoint | sub("^[A-Z_]+://"; "")')

cat > link.properties <<'EOF'
consumer.offset.sync.enable=true
consumer.offset.group.filters={"groupFilters":[{"name":"*","patternType":"LITERAL","filterType":"INCLUDE"}]}
acl.sync.enable=true
acl.filters={"aclFilters":[{"resourceFilter":{"resourceType":"any","patternType":"any"},"accessFilter":{"operation":"any","permissionType":"any"}}]}
EOF

confluent kafka link create dedicated-to-enterprise \
  --cluster "$ENTERPRISE_LKC" --environment "$ENV" \
  --source-cluster "$LKC" \
  --source-bootstrap-server "$DEDICATED_BOOTSTRAP" \
  --source-api-key "$KAFKA_KEY" --source-api-secret "$KAFKA_SECRET" \
  --config link.properties

# once per topic you are moving
confluent kafka mirror create orders --link dedicated-to-enterprise \
  --cluster "$ENTERPRISE_LKC" --environment "$ENV"
ACL sync works only between two clusters in the same Confluent Cloud organization. If the Dedicated cluster is privately networked, a link from it works only in certain network combinations, so check Confluent's supported combinations for Cluster Linking over private networking before you build the Enterprise cluster. The link itself bills too. As read in September 2026, that was a base $0.25 an hour on each cluster for internet-networked clusters and $0.50 for privately networked ones in the same cloud, with cross-cloud private links costing more. On top of that came a base $0.25 for every GB the Dedicated cluster sends across the link, and a per-GB link write rate, set by cluster type, on the Enterprise side. Those link rates replace standard Kafka ingress and egress for the mirrored bytes rather than adding to them, and a regional multiplier applies to all of them. Mirroring 2 TB of retained data is about $512 of link egress before a single client moves, so shorten retention on topics that do not need their history first.
The cutover needs a short pause on writes. Stop the producers and consumers for a set of topics, then promote the mirrors:
confluent kafka mirror promote orders --link dedicated-to-enterprise \
  --cluster "$ENTERPRISE_LKC" --environment "$ENV" --dry-run
Run it without --dry-run once the check passes. Promote checks for mirroring, configuration and consumer offset lag between the two topics, then turns the mirror into an ordinary writable topic. Start the clients again against the Enterprise bootstrap endpoint and their new API keys.
Your rollback window closes at promote. Until then the Dedicated cluster is untouched, and pointing clients back at it is a config change. After promote, a one-way link has no undo, because the truncate-and-restore command that reverses a promote exists only on bidirectional links. Keep the Dedicated cluster running through a full business cycle on Enterprise, then delete it, since it bills every CKU until you do.
A quick decision tree
graph TD
  A[Dedicated cluster on the Confluent bill] --> B{Busiest minute needs fewer CKUs than it has?}
  B -- Yes --> C[Shrink one CKU at a time, floor 2 if multi-zone]
  B -- No --> D{Busy hours a small slice of the day?}
  C --> D
  D -- No --> E[Keep Dedicated at this size]
  D -- Yes --> F{Clients unable to move to PrivateLink, or transactional topics?}
  F -- Yes --> E
  F -- No --> G{CKU-hours x your rate above eCKU-hours x eCKU rate?}
  G -- No --> E
  G -- Yes --> H[Cluster-link to Enterprise, promote, then delete Dedicated]
Related reading
Capacity you reserve by the hour behaves the same way wherever you buy it.
- Bedrock provisioned throughput bills when idle is the same reserved-unit problem on model inference, with a commitment term that stops you deleting early.
- Cut Kubernetes costs by right-sizing pod requests sizes to a measured peak one layer down, where the requests you set decide how many nodes you pay for.
- AWS Savings Plans: 73% utilization is break-even works through the break-even for an hourly commitment that bills whether or not you use it.
Common questions
Can I convert a Confluent Cloud Dedicated cluster to Enterprise or Standard?
No. The only in-place type change Confluent supports is upgrading Basic to Standard. Leaving Dedicated means creating the new cluster, mirroring or replaying its topics, moving clients to the new bootstrap endpoint and API keys, and deleting the Dedicated cluster, which keeps billing until you do.
How much does Cluster Linking cost for a migration?
A cluster link bills by the hour on both the source and the destination cluster, plus a per-GB rate on the bytes it carries: egress on the cluster that sends them and a write rate, set by cluster type, on the cluster that receives them. Those per-GB rates replace standard Kafka ingress and egress for the mirrored data, and topic configs, consumer offsets and ACLs synced over the link bill at the same rate. At the base prices read in September 2026 ($0.25 a link-hour on each internet-networked cluster, $0.50 privately networked, and $0.25 per GB sent), mirroring 2 TB of retained data costs about $512 in egress alone. Shorten retention on topics that do not need their history before you create the link.
Does shrinking a Dedicated Confluent cluster cause downtime?
No. Confluent rebalances partitions onto the remaining brokers and says performance remains stable during a resize, though clients can see leader elections, which supported Kafka clients handle. Each CKU typically takes 30 to 60 minutes to remove, and billing drops to the new CKU count in the hour after the change.
What is the minimum size of a Dedicated Confluent cluster?
One CKU for a single-zone cluster and 2 CKUs for a multi-zone cluster. The 99.99% uptime SLA requires multi-zone, and a cluster's zone layout cannot be changed after it is created.
Does Confluent Cloud offer a 99.99% uptime SLA on Dedicated clusters?
Yes, but only on a multi-zone Dedicated cluster. A single-zone Dedicated cluster is covered at 99.95%. Multi-zone needs at least 2 CKUs, which is 1,460 CKU-hours a month, and because the zone layout is fixed at creation, moving a single-zone cluster to four nines means creating a new multi-zone cluster and migrating to it. Standard and Enterprise clusters reach the same 99.99% SLA with a minimum of 2 eCKUs.
How much traffic does one CKU handle?
Confluent publishes 60 MBps of ingress, 180 MBps of egress, 4,500 partitions, 18,000 client connections and 15,000 requests per second per CKU. Partitions are a fixed limit. Throughput, connections and requests are guidelines that depend on the rest of the workload, so check the cluster load metric before sizing to them.
Does an idle Enterprise or Standard cluster cost nothing?
An Enterprise or Standard cluster costs nothing only when every billed dimension sits at zero, which means no topics or partitions and no ingress, egress, connections, connection attempts or requests. A cluster that still has topics pays its minimum eCKU count for every hour.
How much does a Confluent Dedicated cluster cost per CKU?
Confluent does not publish a public price for the Dedicated CKU. Run confluent billing price list with --cluster-type dedicated, --metric KafkaNumCKUs and your cloud and region to get the list rate for your own account. For the rate you pay after discounts, divide amount by quantity across your KAFKA_NUM_CKUS lines from the Costs API.
How OhChimp approaches this
OhChimp reads your real billed Confluent costs from the Billing API with an org-level Cloud API key, splits them by product and cluster, and joins them to your environment and cluster inventory. It flags Dedicated clusters whose billed Kafka spend is low for the tier and drafts a plan to weigh each one against a per-usage cluster, and that plan asks you to confirm peak throughput and private networking needs before anything changes. Every plan carries a risk level and rollback steps, and nothing moves until you press apply. The billed spend behind each flag is real, while the saving after a tier move stays an estimate that OhChimp cannot yet measure. The Confluent integration page covers the key it needs and the other Confluent levers it checks.