Databricks jobs compute lists 73% under all-purpose
Published · Updated · OhChimp Engineering
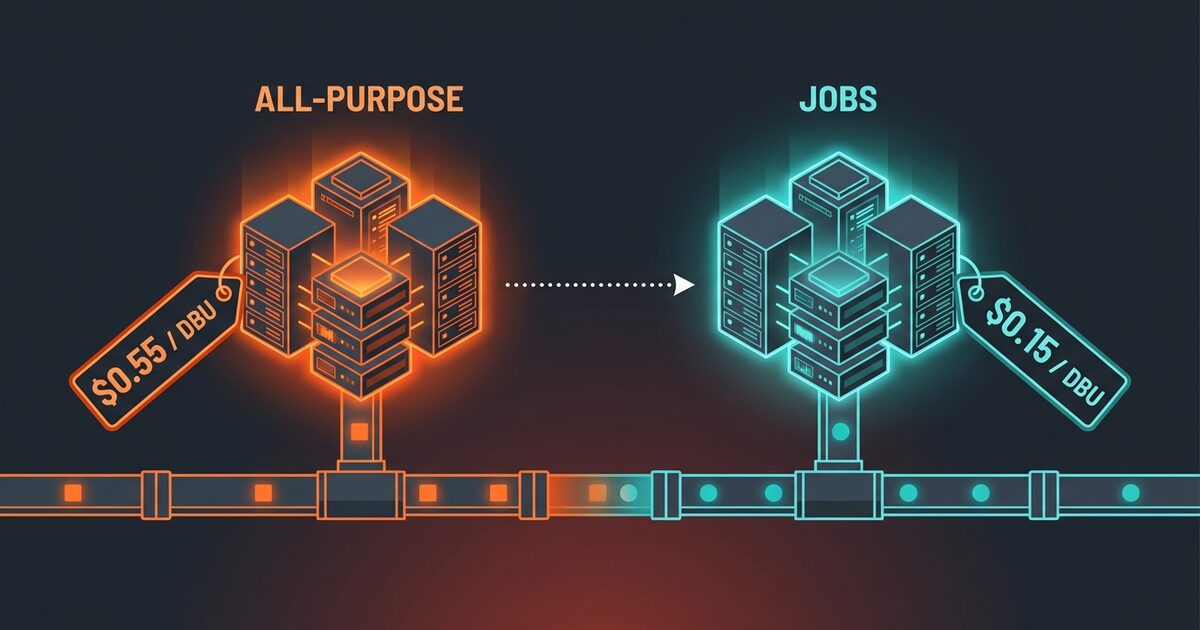
Databricks lists all-purpose compute at $0.55 a DBU and jobs compute at $0.15, so the same code on the same machines costs 73% less on the Databricks line depending on one field in the job definition.
Why all-purpose compute costs more than jobs compute
Databricks bills you in two places: your cloud provider charges for the instances, and Databricks charges for DBUs. A DBU, or Databricks Unit, is a normalized measure of processing power consumed per hour, and its dollar rate is set by which product the compute is filed under.
Here are the AWS list rates on the Premium tier in US East (N. Virginia), for the four ways a job can run.
| Compute | List rate | Cloud instances |
|---|---|---|
| Classic all-purpose | $0.55 per DBU | billed separately by AWS |
| Classic jobs | $0.15 per DBU | billed separately by AWS |
| Serverless all-purpose | $0.75 per DBU | included |
| Serverless jobs | $0.35 per DBU | included |
A given node type emits the same DBUs per hour whichever product it sits under, and your cloud provider charges the same hourly rate either way. The entire gap between $0.55 and $0.15 sits on the Databricks line.
One field decides which line a run lands on. Databricks says so in its Jobs API reference: "When you run a job on a new jobs cluster, the job is treated as a Jobs Compute (automated) workload subject to Jobs Compute pricing. When you run a job on an existing all-purpose cluster, it is treated as an All-Purpose Compute (interactive) workload subject to All-Purpose Compute pricing."
A task carrying existing_cluster_id points at a cluster somebody created by hand. A task carrying new_cluster, or a job_cluster_key pointing into the job's job_clusters block, gets a cluster built for the run and torn down after it. The first pays $0.55 and the second $0.15. Everything else about the run is identical.
Photon narrows that gap without closing it. Databricks publishes Photon as a DBU emission rate rather than a price, and the multiplier differs by product: all-purpose classic emits 2x the DBUs of the same non-Photon cluster, jobs classic emits 2.9x. An hour that would emit one DBU without Photon therefore costs 2 times $0.55 on all-purpose, and 2.9 times $0.15 on job compute. That is $1.10 against $0.435, so the discount lands at 60% rather than 73%.
Databricks' own compute guidance for jobs says of running production work on all-purpose compute: "Databricks does not recommend this configuration for production jobs."
The startup tax that inverts the math on short jobs
A job cluster does not exist until the run starts. Databricks puts classic job cluster startup at four to six minutes, and you pay DBUs for those minutes. A warm all-purpose cluster is already up, so a run landing on it pays for its own runtime and nothing else.
Call the run time t and the startup s. On the warm cluster the run costs 0.55t. On a fresh job cluster it costs 0.15(s + t). Job compute wins when 0.15(s + t) falls below 0.55t, which resolves to t > 0.375s. At a five minute startup that threshold is a run time of about one minute fifty.
A job that finishes in under roughly two minutes costs more on job compute than on an all-purpose cluster that was already running.
Take a 45 second task on a 15 minute schedule, so 96 runs a day. Landing on a warm all-purpose cluster it bills 72 minutes of DBU time a day at $0.55. Building its own cluster with a five minute start, it bills 552 minutes a day at $0.15. Per DBU-hour of cluster capacity that is $0.66 a day against $1.38, so job compute costs twice as much. The instance bill climbs further, because those nodes now run 9.2 hours a day instead of 1.2.
That arithmetic holds only while somebody else keeps the cluster warm. Point the same job at a cluster that exists for nothing else and it inverts. Auto-termination measures idle time, and a job every 15 minutes never lets a 60 minute idle window elapse, so the cluster runs around the clock at $0.55.
| Where the 45 second job runs | Billed hours a day | Cost per DBU-hour of capacity |
|---|---|---|
| A job cluster built per run | 9.2 | $1.38 |
| An all-purpose cluster people also use | 1.2 | $0.66 |
| An all-purpose cluster only this job keeps alive | 24 | $13.20 |
The middle row is the only one where the interactive rate wins, and it wins by charging the idle hours to whoever else is on that cluster. Find out who that is before you book it as a saving. The bottom row is nine times the cost of job compute for a workload that is busy 5% of the day, which is the same idle-capacity problem Snowflake warehouses have when AUTO_SUSPEND is set too generously.
Paying to keep capacity warm so a workload starts fast is the trade Cloud Run makes with minimum instances, and it settles the same way here. Price the idle hours first, then decide whether the warm path is actually the cheap one.
Find your all-purpose job runs by hand
system.billing.usage records metered usage per SKU, and system.billing.list_prices carries your account's own rates, one row per SKU and unit, with price_end_time null on the rate in force today.
SELECT
  u.sku_name,
  SUM(u.usage_quantity)                     AS dbus,
  SUM(u.usage_quantity * p.pricing.default) AS list_cost_usd
FROM system.billing.usage u
JOIN system.billing.list_prices p
  ON  u.sku_name   = p.sku_name
  AND u.usage_unit = p.usage_unit
  AND p.price_end_time IS NULL
WHERE u.usage_date >= date_sub(current_date(), 30)
GROUP BY u.sku_name
ORDER BY list_cost_usd DESC;
pricing.default is the undiscounted list price, so a negotiated contract reads high here. Add up PREMIUM_ALL_PURPOSE_COMPUTE and PREMIUM_ALL_PURPOSE_COMPUTE_(PHOTON), or their ENTERPRISE_ equivalents. Their share of the total is the ceiling on what this change can move, and if the platform runs production then every dollar of it is cost of revenue rather than overhead.
Naming the responsible jobs takes a different tool, and the reason is the same field you are hunting. A shared cluster runs notebooks, SQL and several jobs at once, so Databricks attributes each hourly usage record to the cluster rather than to any one run. usage_metadata.job_id populates for job and serverless compute, where a cluster belongs to a single run. Putting a job on an interactive cluster costs you per-job cost attribution on top of the rate, which is why the query above can size the problem but cannot itemize it.
The job definitions still know, so sweep them with the Databricks CLI.
databricks jobs list -o json | jq -r '.[].job_id' | while read -r job_id; do
  databricks jobs get "$job_id" -o json | jq -r --arg job_id "$job_id" '
    .settings
    | select(.existing_cluster_id != null or any(.tasks[]?; .existing_cluster_id != null))
    | [ $job_id,
        .name,
        ([.existing_cluster_id] + [.tasks[]?.existing_cluster_id]
           | map(select(. != null)) | unique | join(",")) ]
    | @tsv'
done
Every row is a scheduled job billing at the interactive rate. Multi-task jobs carry the field on each task, and older single-task jobs carry it at the top of settings, so the filter checks both places.
Then measure how long each one actually runs, because that decides whether moving it saves anything. Run times come back as epoch milliseconds.
databricks jobs list-runs --job-id 620182517923142 --limit 25 -o json \
  | jq -r '.runs[]
      | [ .run_id, ((.end_time - .start_time) / 60000 | floor) ]
      | @tsv'
Compare the median against the four to six minutes a job cluster spends starting. Then check whether the cluster it currently uses has a human on it, or whether this job is the only reason it is switched on.
Move a job onto job compute with a rollback
databricks jobs reset replaces a job's settings wholesale, so save the current ones first. That file is your rollback.
JOB_ID=620182517923142
databricks jobs get "$JOB_ID" -o json | jq '.settings' > "job-$JOB_ID.before.json"
Copy the shape of the cluster you are leaving, so the replacement runs the same runtime on the same node type.
databricks clusters get 0405-123456-abcd1234 -o json \
  | jq '{spark_version, node_type_id, num_workers}'
Rewrite the settings with those values: declare a job cluster, and point every task at it instead of the interactive one.
jq '
  .job_clusters = [{
    job_cluster_key: "etl",
    new_cluster: {
      spark_version: "15.4.x-scala2.12",
      node_type_id: "m5d.large",
      num_workers: 4
    }
  }]
  | del(.existing_cluster_id)
  | .tasks = [ .tasks[] | del(.existing_cluster_id) | .job_cluster_key = "etl" ]
' "job-$JOB_ID.before.json" > "job-$JOB_ID.after.json"
Feed the rewritten file to databricks jobs reset.
databricks jobs reset --json "$(jq -n \
  --arg job_id "$JOB_ID" \
  --slurpfile settings "job-$JOB_ID.after.json" \
  '{job_id: ($job_id | tonumber), new_settings: $settings[0]}')"
The next scheduled run builds its own cluster and bills at $0.15. A run already in flight finishes on the old cluster, so nothing is interrupted.
Rolling back is the same call against the file you saved.
databricks jobs reset --json "$(jq -n \
  --arg job_id "$JOB_ID" \
  --slurpfile settings "job-$JOB_ID.before.json" \
  '{job_id: ($job_id | tonumber), new_settings: $settings[0]}')"
Libraries do not travel with the job. A shared cluster usually has packages installed on it directly, and a fresh job cluster starts bare, so a task that imports one of them fails on its first run. Read the source cluster's list and declare what the task needs in the job definition before you cut over.
databricks libraries cluster-status 0405-123456-abcd1234 -o jsonA quick decision tree
graph TD
  A[Scheduled job on an all-purpose cluster] --> B{Does that cluster exist for people too?}
  B -- No --> C[Move to job compute: it bills only while the job runs]
  B -- Yes --> D{Median run time over about 2 minutes?}
  D -- Yes --> C
  D -- No --> E{Can the runs be batched onto a longer schedule?}
  E -- Yes --> F[Batch first, then move to job compute]
  E -- No --> G[Serverless jobs: starts in under a minute, no cluster to keep warm]
Common questions
Is Databricks jobs compute cheaper than all-purpose compute?
Yes, by a wide margin on the Databricks line. On AWS Premium in US East (N. Virginia), classic jobs compute lists at $0.15 per DBU against classic all-purpose at $0.55, so the same work costs about 73% less. Your cloud provider charges the same hourly instance rate either way, so the whole difference is the DBU rate. With Photon the gap narrows to about 60%, because Photon emits 2x the DBUs on all-purpose and 2.9x on job compute.
Why is my scheduled job billing at the all-purpose rate?
Because its task points at a cluster that already exists. Databricks documents that a job run on an existing all-purpose cluster is treated as an interactive workload and priced accordingly, while a job that creates its own cluster is priced as Jobs Compute. Look for existing_cluster_id on the job's tasks, or at the top of settings on older single-task jobs.
Does moving a job to job compute always save money?
No. A job cluster is created per run and takes four to six minutes to start, and you pay DBUs for that startup. Against an all-purpose cluster that is already running for other people, job compute only pays off above a run time of about 0.375 times the startup, so roughly one minute fifty at a five minute start. If the job is the only thing keeping that cluster alive, job compute wins by a large margin regardless of run time.
Can I see what a single job costs on an all-purpose cluster?
Not accurately. A shared cluster runs notebooks, queries and several jobs at once, so system.billing.usage attributes the hourly record to the cluster rather than to a run, and usage_metadata.job_id comes back null. Per-job attribution works on job compute and serverless compute, where the cluster belongs to a single run.
How do I switch a job to a job cluster without breaking it?
Save the current settings with databricks jobs get, add a job_clusters entry copying the old cluster's spark_version, node_type_id and num_workers, swap each task's existing_cluster_id for a job_cluster_key, then apply with databricks jobs reset. Declare any libraries the shared cluster had installed, since a fresh job cluster starts with none. Rolling back is the same reset call against the settings file you saved.
What about serverless jobs?
Serverless jobs list at $0.35 per DBU with the instance cost included, against $0.15 plus your own instance bill on classic job compute. Databricks puts the Performance Optimized mode's startup at under a minute, against four to six minutes for a classic cluster, which is what makes it the sensible target for short jobs on a tight schedule where the classic startup tax would swamp the rate cut.
How OhChimp approaches this
OhChimp reads your workspace compute list and, when you point it at a SQL warehouse, your system.billing tables. It ranks spend by SKU against your account's own list prices, then flags an all-purpose-heavy mix along with clusters and warehouses left with no auto-shutdown window. Each fix comes back as a plan you read first, carrying its risk level and the steps to undo it. Nothing changes until you press apply. OhChimp has no way yet to measure what moving a job off all-purpose compute saves, so that figure remains an estimate.
Connection details live on the Databricks integration page.